When you write a chain of Spark transformations, Spark usually does not process every row immediately. It records what you asked for and waits until an action requires a result. That delay gives the engine a chance to optimise the whole plan rather than executing each line in isolation.
Transformations describe work
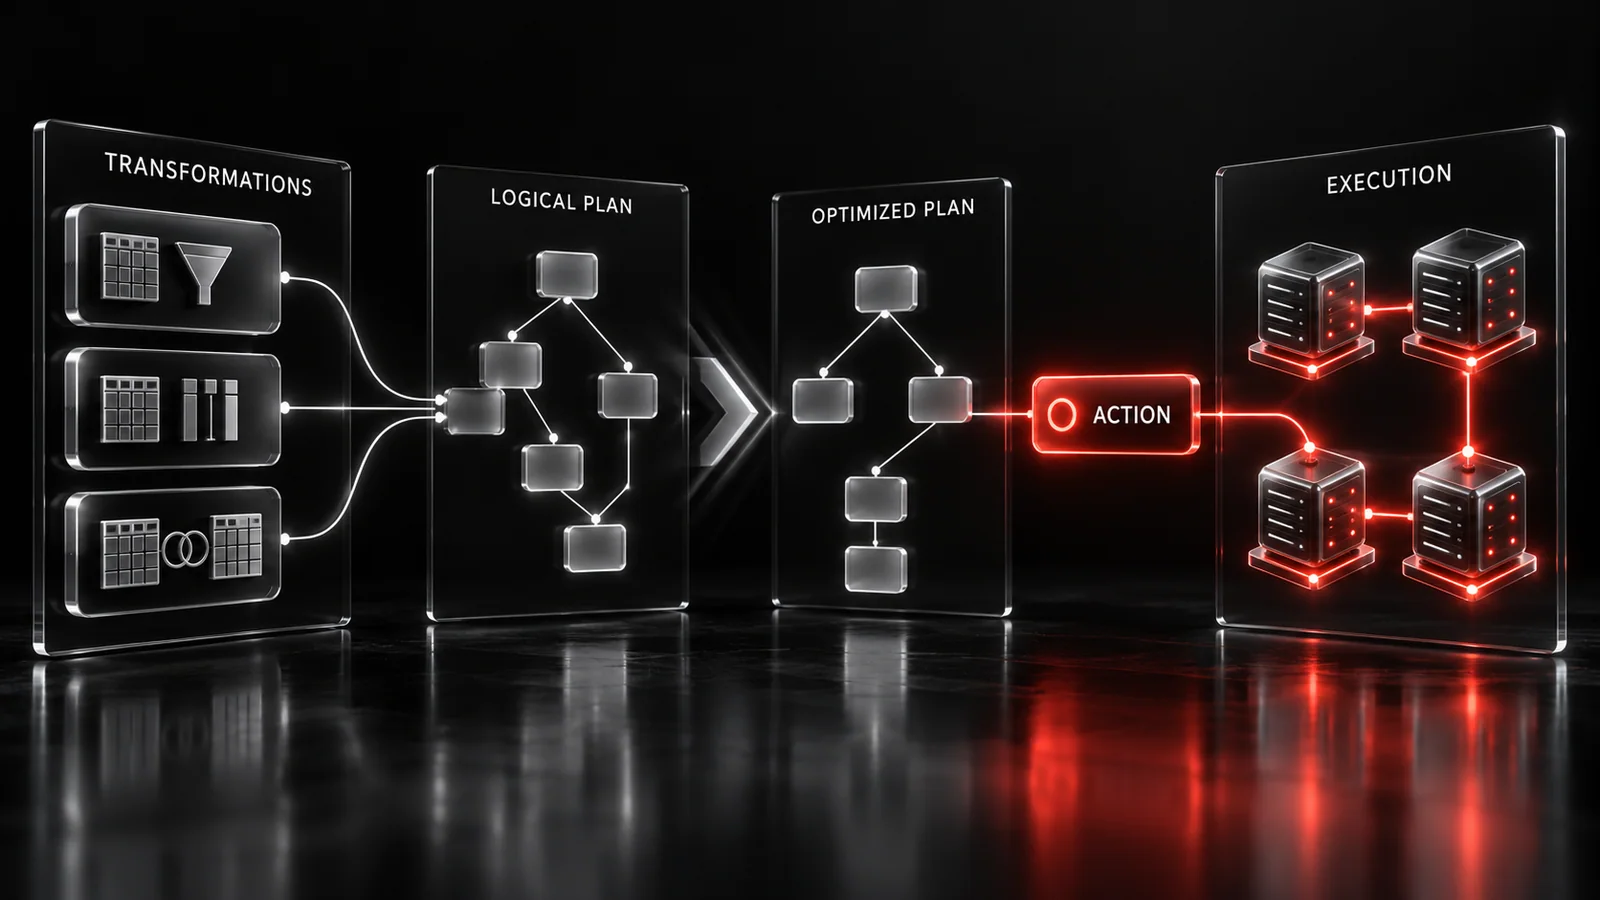
Operations such as select, filter and join produce new DataFrames that represent additional plan nodes. An action such as count, collect or writing output asks Spark to execute enough of the plan to produce a result. Lazy evaluation is therefore about separating a description of work from the moment of execution.
The optimizer sees across lines
Because Spark sees a larger expression, it can push filters closer to the source, remove unused columns and choose physical operators. Not every optimization is possible, and user-defined code can hide useful information, but the plan is still a better optimization boundary than one Python line at a time.
Your notebook is written top to bottom; Spark executes a planned graph shaped by dependencies and actions.
One action can create several stages
The physical plan is divided around boundaries that require data redistribution. Work that can be pipelined within partitions may stay in one stage; a shuffle normally separates stages. Each stage runs tasks across its partitions, subject to available execution slots.
events = spark.table("main.events.raw")
result = (events
    .filter("event_date >= current_date() - 7")
    .groupBy("event_type")
    .count())

result.explain(mode="formatted")
result.show()
The transformations construct the plan. explain lets you inspect it, while show requests rows and therefore triggers execution.
Caching changes repeated execution
Without persistence, a later action can recompute upstream work. Caching can help when the same expensive intermediate result is reused, but it also consumes memory and can evict other useful data. Cache only after measuring repeated work and unpersist it when the reuse window ends.
Lazy evaluation prevents unnecessary work; careless repeated actions can still request the same expensive work many times.
Go to the source
Keep learning with the official documentation.
Apache Spark: RDD programming guide ↗Apache Spark: SQL performance tuning ↗