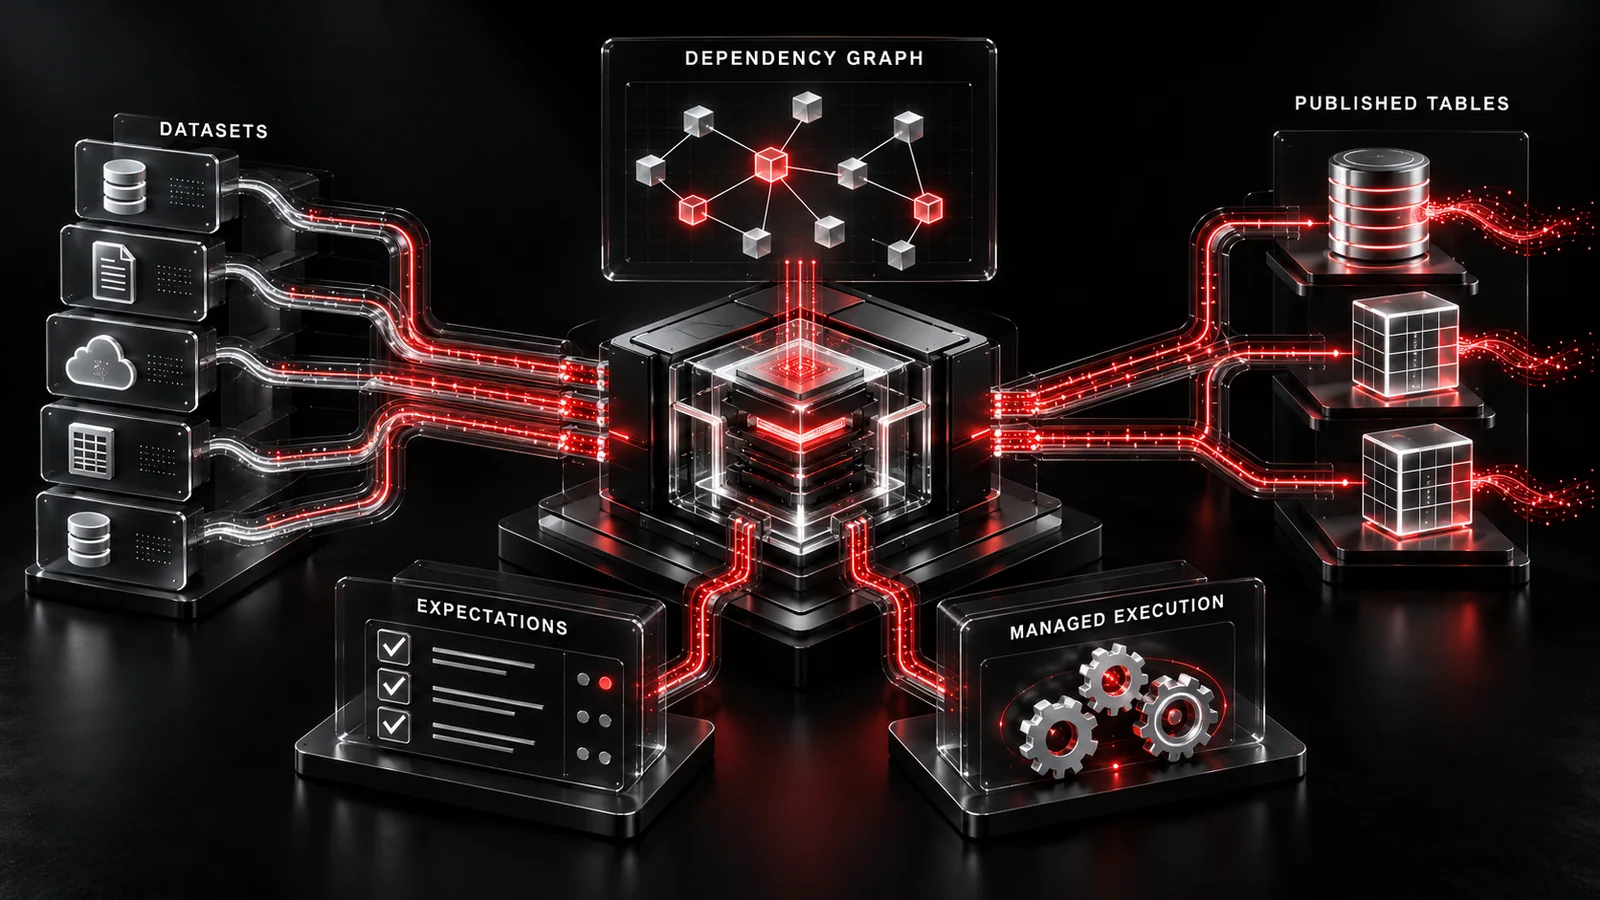
In an imperative pipeline you write the sequence of reads, transformations, writes and retries. In Lakeflow Spark Declarative Pipelines, you describe datasets and their relationships. The service builds and runs the dependency graph, but you still own the data contracts and operational intent.
Declare datasets, not task order
A pipeline analyses dataset definitions and their dependencies to determine execution order. That removes some manual orchestration code, but it does not remove architecture decisions. You still decide the table grain, source semantics, quality rules, update mode and what downstream users may trust.
Choose the right dataset type
Streaming tables are suited to incrementally arriving data and maintain streaming progress. Materialized views maintain query results and can refresh incrementally when supported. Views store a query definition without materializing its result. The right choice follows the source and consumption contract—not a preference for one API.
Declarative does not mean automatic correctness. It means the platform can operate more of the execution because you stated the desired result clearly.
Expectations make quality visible
Expectations express conditions that records should satisfy. Depending on the policy, invalid rows can be observed, dropped or cause an update to fail. Use them for explicit, measurable data contracts rather than as a replacement for understanding source defects.
from pyspark import pipelines as dp

@dp.table
@dp.expect_or_drop("valid_order_id", "order_id IS NOT NULL")
def orders_clean():
    return spark.readStream.table("bronze.orders")
This simplified example communicates intent: publish a streaming table and reject rows without an order identifier. Production rules should also cover uniqueness, valid amounts, event time and late-arriving updates.
Operate the contract
A healthy pipeline needs observable freshness, quality results, lineage and a controlled recovery plan. When a rule changes, determine which historical data must be recomputed and which downstream tables depend on it. Declarative execution makes this graph clearer; it does not decide the business answer.
The pipeline should tell operators what is late, what was rejected, and what will be recomputed before they press retry.
Go to the source
Keep learning with the official documentation.
Databricks: Lakeflow Spark Declarative Pipelines ↗Databricks: expectations ↗