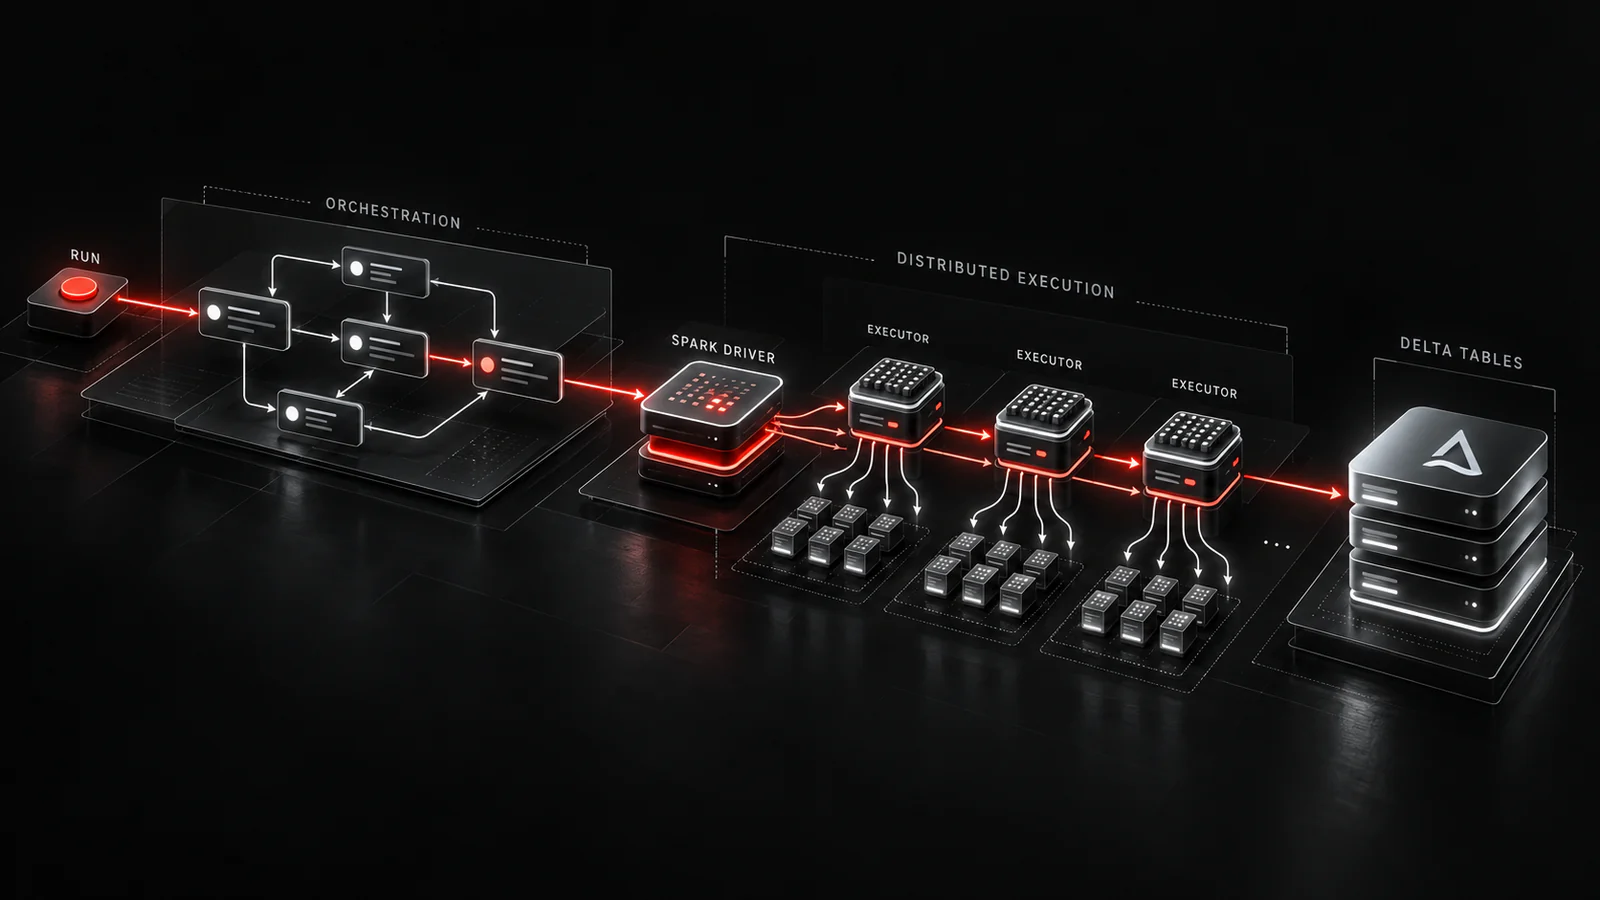
The Run button hides several different systems. Understanding their boundaries turns a mysterious failure into a question you can investigate: did the workflow fail, did compute fail, or did the data operation fail?
A workflow is not a Spark job
A Lakeflow Job coordinates tasks and their dependencies. A task might execute a notebook, a SQL query, or another supported workload. Inside a Spark application, an action can trigger one or more Spark jobs. The two uses of “job” describe different layers: workflow orchestration above, distributed execution below.
Debug the layer that actually failed. A task waiting on a dependency is not the same as a slow Spark stage.
The driver coordinates; executors do the work
For a Spark workload, the driver coordinates the application and schedules tasks. Executors run those tasks and can retain data in memory or on disk. Tasks operate on partitions; they are not copies of the entire dataset. SQL workloads may use different execution paths, so do not assume every Databricks task has this exact topology.
A practical investigation
Imagine a daily orders workflow that suddenly takes 30 minutes instead of five. First inspect its task timeline. If most time is before execution, investigate compute startup or scheduling. If one transformation dominates, open its execution details. A handful of unusually slow tasks suggests uneven work; a broad slowdown could indicate greater input volume or an expensive shuffle. These are hypotheses to test, not diagnoses from runtime alone.
orders = spark.table("main.sales.orders")
summary = orders.groupBy("country").count()
summary.explain(mode="formatted")
summary.show()
In this illustrative PySpark example, defining summary constructs a plan; show requests results. Inspect the plan to understand the aggregation rather than guessing from the number of lines of code.
Make a rerun safe
Consider a task that writes data successfully but fails before reporting completion. A blind retry of an append can duplicate the output. Design the write around a stable business key, a batch identity, or a controlled replacement of the intended slice. Exactly which method is appropriate depends on the table grain and late-arriving updates. Also record enough context—input range, output count, and run identity—to explain what happened.
A successful run is useful. A run you can safely repeat is production-ready.
Go to the source
Keep learning with the official documentation.
Databricks: Lakeflow Jobs ↗Apache Spark: cluster overview ↗